The Problem
You trained a language model on the next-token-prediction objective. It writes grammatical English. It also lies, rambles, and refuses to refuse. You cannot fix this with more pretraining — web text is the problem, not the cure.
You want a scalar reward that says "response A is better than response B for instruction X." Writing that reward function by hand is impossible. "Helpfulness" is not a closed-form expression over tokens. But humans can compare two outputs and mark a preference. That is cheap to collect at scale.
RLHF (Christiano et al. 2017; Ouyang et al. 2022) converts preferences into a reward model, then optimizes the LM via PPO against that reward. In three steps: SFT → RM → PPO. It is the recipe that shipped ChatGPT, Claude, Gemini, and every other aligned-LLM in 2023–2025.
In 2026 the PPO step is mostly replaced by DPO (Phase 10 · 08) because it is cheaper and nearly as good for alignment tuning. But the reward model piece still underlies every Best-of-N sampler, every RL-from-verifiable-rewards pipeline, and every reasoning model using a process reward model. Understand RLHF and you understand the entire alignment stack.
The Concept
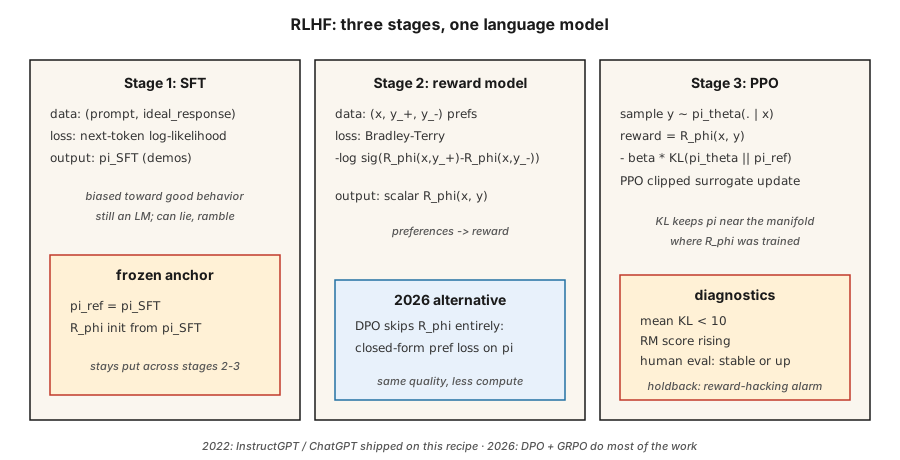
Stage 1: Supervised Fine-Tuning (SFT). Start from a pretrained base model. Fine-tune on human-written demonstrations of the target behavior (instruction-following responses, helpful replies, etc.). Result: a model \pi_{\text{SFT}} that is biased toward good behavior but still has an unbounded action space.
Stage 2: Reward Model training.
- Collect pairs of responses (y_+, y_-) to prompts x, labeled by humans as "y_+ is preferred over y_-."
- Train a reward model R_\phi(x, y) to assign higher scores to y_+.
- Loss: the Bradley-Terry pairwise logistic:
L(\phi) = -\mathbb{E}[ \log \sigma(R_\phi(x, y_+) - R_\phi(x, y_-)) ]
\sigma is the sigmoid. The difference in reward implies a log-odds of preference. BT has been the standard since 1952 (Bradley-Terry) and is the dominant choice in modern RLHF.
- R_\phi is usually initialized from the SFT model with a scalar head on top. Same transformer backbone; a single linear layer outputs the reward.
Stage 3: PPO against the RM with KL penalty.
- Initialize the trainable policy \pi_\theta from \pi_{\text{SFT}}. Keep a frozen reference \pi_{\text{ref}} = \pi_{\text{SFT}}.
- Reward at the end of a response y:
r_{\text{total}}(x, y) = R_\phi(x, y) - \beta \cdot \mathrm{KL}(\pi_\theta(\cdot \mid x) \Vert \pi_{\text{ref}}(\cdot \mid x))
The KL penalty prevents \pi_\theta from drifting arbitrarily from \pi_{\text{SFT}} — it is a regularizer, not a hard trust region. \beta typically 0.01-0.05.
- Run PPO (Lesson 08) with this reward. Advantages are computed on the token-level trajectory, but the RM scores only the full response.
Why the KL? Without it, PPO will happily find reward-hacking strategies — the RM was only trained on in-distribution completions. An out-of-distribution response might score higher than any human-written one. The KL keeps \pi_\theta near the manifold where the RM was trained. It is the single most important knob in RLHF.
2026 status:
- DPO (Rafailov 2023): closed-form algebra collapses Stage 2+3 into a single supervised loss over preference data. No RM, no PPO. Same quality on alignment benchmarks for a fraction of the compute. Covered in Phase 10 · 08.
- GRPO (DeepSeek 2024–2025): PPO with a group-relative baseline instead of a critic, reward from a verifier (code runs / math answer matches) instead of a human-trained RM. Dominant for reasoning models. Covered in Phase 9 · 12.
- Process reward models (PRMs): score partial solutions (each reasoning step), used in both RLHF and GRPO variants for reasoning.
- Constitutional AI / RLAIF: use an aligned LLM to generate preferences instead of humans. Scales the preference budget.
Build It
This lesson uses tiny synthetic "prompts" and "responses" represented as strings. The RM is a linear scorer over a bag-of-tokens representation. No real LLM — the shape of the pipeline matters, not the scale. See code/main.py.
Step 1: synthetic preference data
pythonPROMPTS = ["help me", "answer me", "explain this"]
GOOD_WORDS = {"clear", "specific", "kind", "thorough"}
BAD_WORDS = {"vague", "rude", "wrong", "short"}
def make_pair(rng):
x = rng.choice(PROMPTS)
y_good = rng.choice(list(GOOD_WORDS)) + " " + rng.choice(list(GOOD_WORDS))
y_bad = rng.choice(list(BAD_WORDS)) + " " + rng.choice(list(BAD_WORDS))
return (x, y_good, y_bad)In real RLHF this is replaced by human labelers. The shape — (prompt, preferred_response, rejected_response) — is identical.
Step 2: Bradley-Terry reward model
Linear score: R(x, y) = w · bag(y). Train to minimize the BT pairwise log-loss:
pythondef rm_train_step(w, x, y_pos, y_neg, lr):
r_pos = dot(w, bag(y_pos))
r_neg = dot(w, bag(y_neg))
p = sigmoid(r_pos - r_neg)
for tok, cnt in bag(y_pos).items():
w[tok] += lr * (1 - p) * cnt
for tok, cnt in bag(y_neg).items():
w[tok] -= lr * (1 - p) * cntAfter a few hundred updates, w assigns positive weights to good-word tokens and negative to bad.
Step 3: PPO-like policy on top of RM
Our toy policy produces a single token from a vocabulary. We score the token under the RM, compute \log \pi_\theta(\text{token} \mid \text{prompt}), add a KL-to-reference penalty, and apply the clipped PPO surrogate.
pythondef rlhf_step(theta, ref, w, prompt, rng, eps=0.2, beta=0.1, lr=0.05):
logits_theta = policy_logits(theta, prompt)
probs = softmax(logits_theta)
token = sample(probs, rng)
logits_ref = policy_logits(ref, prompt)
probs_ref = softmax(logits_ref)
reward = dot(w, bag([token])) - beta * kl(probs, probs_ref)
# ppo-style update on theta, treating reward as the return
...Step 4: monitor the KL
Track mean \mathrm{KL}(\pi_\theta \Vert \pi_{\text{ref}}) every update. If it creeps past ~5-10 the policy has drifted far from \pi_{\text{SFT}} — lower \beta is rising or reward hacking is starting. This is the top diagnostic in real RLHF.
Step 5: the production recipe with TRL
Once you understand the toy pipeline, here is the same loop as a real library user writes it. Hugging Face's TRL is the reference implementation — RewardTrainer for Stage 2 and PPOTrainer (with a KL-to-reference built in) for Stage 3.
python# Stage 2: reward model from pairwise preferences
from trl import RewardTrainer, RewardConfig
from transformers import AutoModelForSequenceClassification, AutoTokenizer
tok = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
rm = AutoModelForSequenceClassification.from_pretrained(
"meta-llama/Llama-3.1-8B-Instruct", num_labels=1
)
# dataset rows: {"prompt", "chosen", "rejected"} — Bradley-Terry format
trainer = RewardTrainer(
model=rm,
tokenizer=tok,
train_dataset=preference_data,
args=RewardConfig(output_dir="./rm", num_train_epochs=1, learning_rate=1e-5),
)
trainer.train()python# Stage 3: PPO against the RM with KL penalty to the SFT reference
from trl import PPOTrainer, PPOConfig, AutoModelForCausalLMWithValueHead
policy = AutoModelForCausalLMWithValueHead.from_pretrained("./sft-checkpoint")
ref = AutoModelForCausalLMWithValueHead.from_pretrained("./sft-checkpoint") # frozen
ppo = PPOTrainer(
config=PPOConfig(learning_rate=1.41e-5, batch_size=64, init_kl_coef=0.05,
target_kl=6.0, adap_kl_ctrl=True),
model=policy, ref_model=ref, tokenizer=tok,
)
for batch in dataloader:
responses = ppo.generate(batch["query_ids"], max_new_tokens=128)
rewards = rm(torch.cat([batch["query_ids"], responses], dim=-1)).logits[:, 0]
stats = ppo.step(batch["query_ids"], responses, rewards)
# stats includes: mean_kl, clip_frac, value_loss — the three PPO diagnosticsThree things the library does for you. adap_kl_ctrl=True implements the adaptive-β schedule: if observed KL exceeds target_kl, β doubles; if below half, β halves. The reference model is frozen by convention — you must not accidentally share parameters with policy. And the value head lives on the same backbone as the policy (AutoModelForCausalLMWithValueHead attaches a scalar MLP head), which is why TRL reports policy/kl and value/loss separately.
Pitfalls
- Over-optimization / reward hacking. The RM is imperfect; \pi_\theta finds adversarial completions that score high but are bad. Symptoms: reward climbs indefinitely while human eval score plateaus or drops. Fix: stop early, raise \beta, broaden RM training data.
- Length hacking. RMs trained on helpful responses often implicitly reward length. The policy learns to pad responses. Remediation: length-normalized reward, or RLAIF with a length-aware RM.
- Too-small RM. The RM needs to be at least as large as the policy. A tiny RM cannot faithfully score the policy's outputs.
- KL tuning. Too low β → drift and reward hacking. Too high β → policy barely changes. The standard trick is an adaptive β that targets a fixed KL per step.
- Preference-data noise. ~30% of human labels are noisy or ambiguous. Calibrate by training the RM on agreement-filtered data or use a temperature on BT.
- Off-policy problems. PPO data is slightly off-policy after the first epoch. Monitor clip fraction as in Lesson 08.
Use It
RLHF in 2026 is layered:
| Layer | Target | Method |
|---|---|---|
| Instruction following, helpfulness, harmlessness | Alignment | DPO (Phase 10 · 08) preferred over RLHF-PPO. |
| Reasoning correctness (math, code) | Capability | GRPO with verifier reward (Phase 9 · 12). |
| Long-horizon multi-step tasks | Agentic | PPO / GRPO with process reward models over steps. |
| Safety / refusal behavior | Safety | RLHF-PPO with separate safety RM, or Constitutional AI. |
| Best-of-N at inference | Fast alignment | Use RM at decode time; no policy training needed. |
| Reward distillation | Inference compute | Train a small "reward head" on top of a frozen LM. |
RLHF was the method in 2022–2024. In 2026, production alignment pipelines are DPO-first, PPO-only for the RM-intensive or safety-critical steps.
Ship It
Save as outputs/skill-rlhf-architect.md:
markdown---
name: rlhf-architect
description: Design an RLHF / DPO / GRPO alignment pipeline for a language model, including RM, KL, and data strategy.
version: 1.0.0
phase: 9
lesson: 9
tags: [rl, rlhf, alignment, llm]
---
Given a base LM, a target behavior (alignment / reasoning / refusal / agent), and a preference or verifier budget, output:
1. Stage. SFT? RM? DPO? GRPO? With justification.
2. Preference or verifier source. Humans, AI feedback, rule-based, unit-test-pass, or reward distillation.
3. KL strategy. Fixed β, adaptive β, or DPO (implicit KL).
4. Diagnostics. Mean KL, reward stability, over-optimization guard (holdout human eval).
5. Safety gate. Red-team set, refusal rate, safety RM separate from helpfulness RM.
Refuse to ship RLHF-PPO without a KL monitor. Refuse to use an RM smaller than the target policy. Refuse length-only rewards. Flag any pipeline that does not hold back a blind human-eval set as lacking over-optimization protection.Exercises
- Easy. Train the Bradley-Terry reward model in
code/main.pyon 500 synthetic preference pairs. Measure pairwise accuracy on a held-out 100 pairs. Should exceed 90%. - Medium. Run the toy PPO-RLHF loop with \beta \in \lbrace 0.0, 0.1, 1.0 \rbrace. For each, plot RM score vs KL-to-reference over updates. Which runs reward-hack?
- Hard. Implement DPO (closed-form preference-likelihood loss) on the same preference data and compare to the RLHF-PPO pipeline in compute used and final RM score achieved.
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| RLHF | "Alignment RL" | Three-stage SFT + RM + PPO pipeline (Christiano 2017, Ouyang 2022). |
| Reward Model (RM) | "The scoring net" | Learned scalar function fit to pairwise preferences via Bradley-Terry. |
| Bradley-Terry | "Pairwise logistic loss" | P(y_+ \succ y_-) = \sigma(R(y_+) - R(y_-)); the standard RM objective. |
| KL penalty | "Stay near the reference" | \beta \cdot \mathrm{KL}(\pi_\theta \Vert \pi_{\text{ref}}) in the reward; the anti-reward-hacking regularizer. |
| Reward hacking | "Goodhart's law" | Policy exploits RM flaws; symptoms: reward up, human eval flat. |
| RLAIF | "AI-labeled preferences" | RLHF where labels come from another LM instead of humans. |
| PRM | "Process Reward Model" | Scores partial reasoning steps; used in reasoning pipelines. |
| Constitutional AI | "Anthropic's method" | AI-generated preferences guided by explicit rules. |
Further Reading
- Christiano et al. (2017). Deep Reinforcement Learning from Human Preferences — the paper that started RLHF.
- Ouyang et al. (2022). InstructGPT — Training language models to follow instructions with human feedback — the recipe behind ChatGPT.
- Stiennon et al. (2020). Learning to summarize with human feedback — earlier RLHF for summarization.
- Rafailov et al. (2023). Direct Preference Optimization — DPO; the post-RLHF default in 2026.
- Bai et al. (2022). Constitutional AI: Harmlessness from AI Feedback — RLAIF and self-critique loop.
- Anthropic RLHF paper (Bai et al. 2022). Training a Helpful and Harmless Assistant — the HH paper.
- Hugging Face TRL library — production
RewardTrainerandPPOTrainer. Read the trainer source for the adaptive-KL and value-head details. - Hugging Face — Illustrating Reinforcement Learning from Human Feedback by Lambert, Castricato, von Werra, Havrilla — the canonical walk-through of the three-stage pipeline with diagrams.
- von Werra et al. (2020). TRL: Transformer Reinforcement Learning — the library;
examples/has end-to-end RLHF scripts for Llama, Mistral, and Qwen. - Sutton & Barto (2018). Ch. 17.4 — Designing Reward Signals — the reward-hypothesis view; essential prerequisite for thinking about reward hacking.
Diagrams1 figure