问题
你把一份 50 页的合同放进 RAG 系统。用户问:「终止条款是什么?」检索器返回了封面页。为什么?因为模型是在 512 token 的分块上训练的,而终止条款位于第 20 页,被一个分页符劈成两半,附近又没有能与查询挂上钩的关键词。
解决办法不是「买一个更好的 embedding 模型」,而是分块。块多大?要不要重叠?在哪里切?要不要带上下文?
2026 年 2 月的基准测试给出了令人意外的结果:
- Vectara 2026 年的研究:递归式 512 token 分块以 69% 的准确率击败了语义分块的 54%。
- SPLADE + Mistral-8B 在 Natural Questions 上:重叠没有带来任何可测量的收益。
- 上下文悬崖:上下文到约 2,500 token 时,回答质量急剧下降。
那个「显而易见」的答案(语义分块、20% 重叠、1000 token)往往是错的。本节课帮你建立对六种策略的直觉,并说明何时该用哪一种。
概念
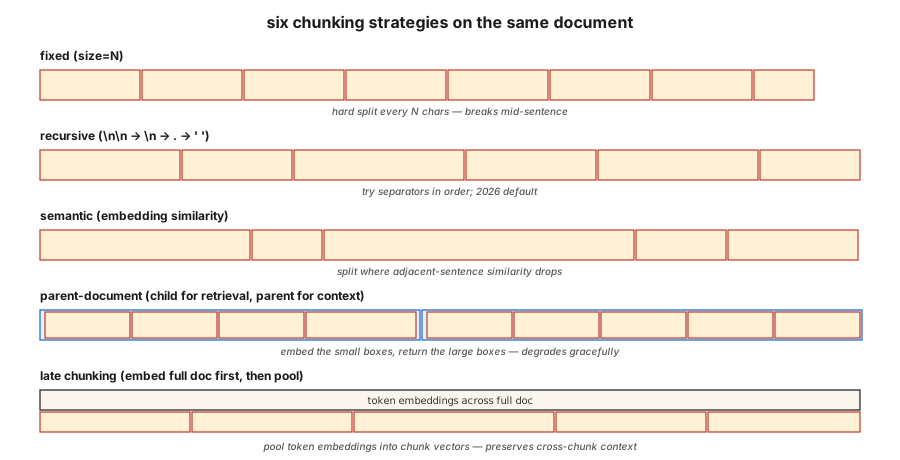
固定分块。 每 N 个字符或 token 切一次。最简单的基线。会在句子中间断开。压缩性好,连贯性差。
递归分块。 LangChain 的 RecursiveCharacterTextSplitter。先尝试按 \n\n 切,然后按 \n,再按 .,最后按空格。回退得很干净。2026 年的默认选择。
语义分块。 对每个句子做 embedding。计算相邻句子的余弦相似度。在相似度低于阈值处切开。能保持主题连贯。速度较慢;有时会产生 40 token 的碎片,反而伤害检索。
句子分块。 按句子边界切分。每块一句,或每块 N 句的窗口。在约 5k token 以内,效果与语义分块相当,成本却低得多。
父文档分块。 既存储用于检索的小块(子块),也存储用于提供上下文的大块(父块)。按子块检索,返回父块。退化得很平缓:子块不好,返回的父块依然合理。
晚期分块(late chunking,2024)。 先在整个文档的 token 级别上做 embedding,再把 token embedding 池化成各分块的 embedding。保留跨块上下文。适用于长上下文 embedder(BGE-M3、Jina v3)。计算量更高。
上下文检索(contextual retrieval,Anthropic,2024)。 给每个分块前置一段由 LLM 生成的摘要,说明它在文档中的位置(「这个分块是终止条款的第 3.2 节……」)。在 Anthropic 自己的基准中带来 35-50% 的检索提升。索引成本高。
胜过一切默认值的规则
让分块大小匹配查询类型:
| 查询类型 | 分块大小 |
|---|---|
| 事实型(「CEO 叫什么名字?」) | 256-512 个 token |
| 分析型 / 多跳 | 512-1024 个 token |
| 整节理解 | 1024-2048 个 token |
这是 NVIDIA 2026 年基准的结论。分块要大到足以容纳答案及本地上下文,小到让检索器的 top-K 结果聚焦于答案,而不是上下文噪声。
构建它
第 1 步:固定分块与递归分块
pythondef chunk_fixed(text, size=512, overlap=0):
step = size - overlap
return [text[i:i + size] for i in range(0, len(text), step)]
def chunk_recursive(text, size=512, seps=("\n\n", "\n", ". ", " ")):
if len(text) <= size:
return [text]
for sep in seps:
if sep not in text:
continue
parts = text.split(sep)
chunks = []
buf = ""
for p in parts:
if len(p) > size:
if buf:
chunks.append(buf)
buf = ""
chunks.extend(chunk_recursive(p, size=size, seps=seps[1:] or (" ",)))
continue
candidate = buf + sep + p if buf else p
if len(candidate) <= size:
buf = candidate
else:
if buf:
chunks.append(buf)
buf = p
if buf:
chunks.append(buf)
return [c for c in chunks if c.strip()]
return chunk_fixed(text, size)第 2 步:语义分块
pythondef chunk_semantic(text, encoder, threshold=0.6, min_chars=200, max_chars=2048):
sentences = split_sentences(text)
if not sentences:
return []
embs = encoder.encode(sentences, normalize_embeddings=True)
chunks = [[sentences[0]]]
for i in range(1, len(sentences)):
sim = float(embs[i] @ embs[i - 1])
current_len = sum(len(s) for s in chunks[-1])
if sim < threshold and current_len >= min_chars:
chunks.append([sentences[i]])
else:
chunks[-1].append(sentences[i])
result = []
for group in chunks:
text_group = " ".join(group)
if len(text_group) > max_chars:
result.extend(chunk_recursive(text_group, size=max_chars))
else:
result.append(text_group)
return result在你的领域上调 threshold。太高 → 碎片。太低 → 一整块巨无霸。
第 3 步:父文档分块
pythondef chunk_parent_child(text, parent_size=2048, child_size=256):
parents = chunk_recursive(text, size=parent_size)
mapping = []
for p_idx, parent in enumerate(parents):
children = chunk_recursive(parent, size=child_size)
for child in children:
mapping.append({"child": child, "parent_idx": p_idx, "parent": parent})
return mapping
def retrieve_parent(child_query, mapping, encoder, top_k=3):
child_embs = encoder.encode([m["child"] for m in mapping], normalize_embeddings=True)
q_emb = encoder.encode([child_query], normalize_embeddings=True)[0]
scores = child_embs @ q_emb
top = np.argsort(-scores)[:top_k]
seen, parents = set(), []
for i in top:
if mapping[i]["parent_idx"] not in seen:
parents.append(mapping[i]["parent"])
seen.add(mapping[i]["parent_idx"])
return parents关键洞察:父块要去重。多个子块可能映射到同一个父块;全部返回会浪费上下文。
第 4 步:上下文检索(Anthropic 模式)
pythondef contextualize_chunks(document, chunks, llm):
context_prompts = [
f"""<document>{document}</document>
Here is the chunk to situate: <chunk>{c}</chunk>
Write 50-100 words placing this chunk in the document's context."""
for c in chunks
]
contexts = llm.batch(context_prompts)
return [f"{ctx}\n\n{c}" for ctx, c in zip(contexts, chunks)]给加了上下文的分块建索引。查询时,检索能从这些额外的周围信号中受益。
第 5 步:评估
pythondef recall_at_k(queries, corpus_chunks, encoder, k=5):
chunk_embs = encoder.encode(corpus_chunks, normalize_embeddings=True)
hits = 0
for q_text, gold_idxs in queries:
q_emb = encoder.encode([q_text], normalize_embeddings=True)[0]
top = np.argsort(-(chunk_embs @ q_emb))[:k]
if any(i in gold_idxs for i in top):
hits += 1
return hits / len(queries)始终做基准测试。对你语料库而言的「最佳」策略,未必和任何一篇博客文章一致。
陷阱
- 只在事实型查询上评估分块。 多跳查询会揭示完全不同的赢家。使用按查询类型分层的评估集。
- 语义分块没有最小长度。 会产生 40 token 的碎片,伤害检索。始终强制
min_tokens。 - 把重叠当迷信。 2026 年的研究发现,重叠往往零收益,还会让索引成本翻倍。要测量,不要假设。
- 不强制最小/最大长度。 5 token 或 5000 token 的分块都会破坏检索。要夹紧。
- 跨文档分块。 绝不要让一个分块横跨两份文档。始终按文档分别分块,再合并。
使用它
2026 年的技术栈:
| 场景 | 策略 |
|---|---|
| 首次构建、语料未知 | 递归,512 token,无重叠 |
| 事实型问答 | 递归,256-512 token |
| 分析型 / 多跳 | 递归,512-1024 token + 父文档 |
| 大量交叉引用(合同、论文) | 晚期分块或上下文检索 |
| 对话 / 会话语料 | 按轮次分块 + 说话人元数据 |
| 短文本(推文、评论) | 一篇文档 = 一个分块 |
从递归 512 开始。在 50 条查询的评估集上测 recall@5。然后据此调优。
交付它
保存为 outputs/skill-chunker.md:
markdown---
name: chunker
description: Pick a chunking strategy, size, and overlap for a given corpus and query distribution.
version: 1.0.0
phase: 5
lesson: 23
tags: [nlp, rag, chunking]
---
Given a corpus (document types, avg length, domain) and query distribution (factoid / analytical / multi-hop), output:
1. Strategy. Recursive / sentence / semantic / parent-document / late / contextual. Reason.
2. Chunk size. Token count. Reason tied to query type.
3. Overlap. Default 0; justify if >0.
4. Min/max enforcement. `min_tokens`, `max_tokens` guards.
5. Evaluation plan. Recall@5 on 50-query stratified eval set (factoid, analytical, multi-hop).
Refuse any chunking strategy without min/max chunk size enforcement. Refuse overlap above 20% without an ablation showing it helps. Flag semantic chunking recommendations without a min-token floor.练习
- 简单。 用 fixed(512, 0)、recursive(512, 0) 和 recursive(512, 100) 对一份 20 页文档分块。比较分块数量和边界质量。
- 中等。 在 5 份文档上构建 30 条查询的评估集。测量递归、语义、父文档三种策略的 recall@5。谁胜出?与博客文章一致吗?
- 困难。 实现上下文检索。测量相对基线递归分块的 MRR 提升。报告索引成本(LLM 调用次数)与准确率收益。
关键术语
| 术语 | 大家常说的 | 实际含义 |
|---|---|---|
| 分块 | 文档的一小段 | 被 embedding、索引和检索的文档子单元。 |
| 重叠 | 安全边距 | 相邻分块共享的 N 个 token;在 2026 年的基准中往往没用。 |
| 语义分块 | 智能分块 | 在相邻句子 embedding 相似度下降处切开。 |
| 父文档分块 | 两级检索 | 检索小的子块,返回大的父块。 |
| 晚期分块 | 先 embedding 再分块 | 在 token 级别对整篇文档做 embedding,再池化成块向量。 |
| 上下文检索 | Anthropic 的技巧 | 索引前给每个分块前置一段 LLM 生成的摘要。 |
| 上下文悬崖 | 2500 token 之墙 | RAG 中上下文约 2.5k token 时观察到的质量下降(2026 年 1 月)。 |
延伸阅读
- Yepes et al. / LangChain — Recursive Character Splitting docs —— 生产中的默认做法。
- Vectara (2024, NAACL 2025). Chunking configurations analysis —— 分块与 embedding 选择同等重要。
- Jina AI — Late Chunking in Long-Context Embedding Models (2024) —— 晚期分块论文。
- Anthropic — Contextual Retrieval —— 用 LLM 生成的上下文前缀把检索提升 35-50%。
- NVIDIA 2026 chunk-size benchmark — Premai summary —— 按查询类型选择分块大小。
示意图共 1 张